The short answer
The standard vocal chain order is cleanup, pitch correction, corrective EQ, compression, de-esser, tone EQ and saturation, then reverb and delay on parallel sends. Clean before you shape, tune before you compress, and add space last.
- 1CleanupNoise reduction, clip gain, high-pass filter
- 2Pitch correctionOn the clean signal, before anything colours it
- 3Corrective EQCut mud, boxiness and resonances
- 4CompressionEven out the level, often in two stages
- 5De-esserTame the S sounds compression brought up
- 6Tone EQ and saturationPresence, air, warmth, density
- 7Limiter or glue (optional)Catch what’s left, keep it dense
- 8Reverb and delayOn parallel sends, not inline
None of this is tradition for its own sake. Every plugin reacts to what it receives, so each stage changes what the next one hears. Below: why each step sits where it does, the three places where engineers genuinely disagree, what changes when you record through the chain, and how to skip the whole puzzle with one plugin.
The numbers in this guide (frequencies, ratios) are common starting points, not laws. Your voice, mic and room decide the rest, and your ears outrank this article. We are a very serious company, but we are not your ears.
Why the order matters
A plugin can only work with the signal it’s given. Put the stages in the wrong order and each one spends its effort on problems the next stage was supposed to remove.
Two examples. A compressor placed before an EQ that cuts a boomy 250 Hz will still react to that boom, pushing the whole vocal down every time it booms, even though you cut the boom right after. And a pitch corrector placed after heavy saturation and reverb has to track a waveform full of extra harmonics and smeared tails, which is how you get glitches and notes jumping to the wrong pitch.
Level matters too. A compressor’s threshold and a saturator’s drive both depend on how loud the signal arrives. Change something early in the chain and everything after it behaves differently, which is why you set a chain from the top down and recheck what follows when you change an early stage.
The vocal chain, step by step
1. Cleanup: noise reduction, clip gain and a high-pass filter
Start by removing what shouldn’t be there: background noise, clicks, plosives and low rumble. Everything after this point will make the noise louder, so this is the cheapest moment to fix it.
Noise reduction goes first, before compression lifts the room noise along with the quiet words. Then clip gain: turn down the few phrases that are far louder than the rest, and up the ones that are far quieter, so the compressor later works on a reasonable range. Finish with a high-pass filter, usually somewhere between 70 and 150 Hz depending on the voice: lower for deep voices, higher for light ones. Raise it until the voice starts to sound thin, then back off a little.
2. Pitch correction
Tune early, on the clean signal. A pitch tracker reads the period of the waveform, and compression, saturation, doubling and reverb all make that waveform harder to read.
Set the key and scale of the song, then decide how audible the correction should be. A fast retune speed snaps notes instantly, which is the hard, obviously tuned sound; a slower one lets the voice glide into pitch so it just sounds in tune. If you do detailed note-by-note editing in a dedicated editor, treat that as an edit, before the chain, and leave the real-time tuner off or gentle.
3. Corrective EQ
Cut problems before the compressor sees them: mud, boxiness and ringing resonances. Cut narrow, and only where you can hear a problem.
Common trouble spots are muddiness somewhere around 200 to 400 Hz, a boxy or nasal tone around 500 Hz to 1 kHz, and harsh ringing between roughly 2 and 5 kHz. Sweep a narrow boost to find the offending frequency, then turn it into a cut. A dynamic EQ is useful here: it only cuts when the resonance actually flares up.
4. Compression
Compression keeps the vocal at a steady level, so the quietest word and the loudest one both sit in front of the music. Two gentle stages usually sound better than one heavy one.
A common pairing is a fast compressor first (FET-style) to catch peaks, followed by a slower one (opto-style) that levels whole phrases, each taking a few decibels rather than one compressor doing all the work. Ratios of about 2:1 to 4:1 are typical starting points. A very fast attack can dull consonants; a release that’s too slow makes the vocal pump against the next word. Match the output level to the input so you judge the sound, not the volume.
5. De-esser
De-ess after compression. Compression raises the quieter parts of the vocal relative to the peaks, and S, T and SH sounds come up with them.
Sibilance usually sits somewhere between about 5 and 10 kHz, higher for most female voices than for most male ones. Find the band where the S sounds spike and reduce only there, only when they spike. Overdo it and the singer starts to lisp, which is a different genre.
6. Tone EQ and saturation
Now shape the character: presence, air, warmth and density. Boosts belong here, after compression, because boosting before a compressor just makes it work harder.
A gentle presence lift somewhere in the 2 to 5 kHz region helps a vocal cut through, and a high shelf from around 10 kHz adds air. Saturation adds harmonics, which makes a vocal sound denser and helps it stay audible on small speakers. Whether saturation goes before or after the tone EQ is taste; try both.
7. Limiter or glue (optional)
A light limiter or multiband compressor at the end catches the peaks the rest of the chain let through and makes the vocal feel dense. Optional for most home mixes, and easy to overdo.
8. Reverb and delay, on sends
Space goes last, and preferably on parallel sends rather than as inserts. The dry vocal stays clear in front, and the effects can be shaped separately.
On the reverb return, a high-pass and low-pass filter keep the tail from muddying the mix, and a little pre-delay keeps consonants intelligible. Delays synced to the tempo (1/4 or 1/8 notes, or a ping-pong) add width without a wash. If you stack doubles or harmonies, process them before the shared reverb, so the whole stack sits in the same room.
Three places where it’s fine to argue
The overall order is settled. These three placements aren’t, and the right answer depends on the voice.
- EQ before or after compression. Both. Cuts before, so the compressor doesn’t react to what you’re removing; boosts after, so they don’t drive the compressor harder. Most chains have an EQ on each side.
- De-esser before or after compression. After is the default. If loud S sounds are triggering the compressor, add a light de-esser in front of it too.
- Saturation early or late. Early, it drives the compressors and sounds more aggressive and vintage; late, it colours the finished vocal and stays easier to control. Both are valid; neither is the one true way.
Recording through the chain vs mixing it
When you record through a chain, keep it light and fast: low latency, gentle compression and tuning if they help the singer, no big reverbs. Record the vocal dry and do the real chain in the mix.
Latency is the delay between singing and hearing yourself back. Most people start to notice it at around 10 ms, and it gets distracting quickly after that. Plugins with lookahead or linear-phase processing add latency, so they belong in the mix, not on the monitoring path. Reverbs and long delays also cost CPU, which forces bigger buffers, which means more latency. Many vocal plugins have a low-latency or tracking mode for exactly this.
Does the order change by genre?
Barely. The order stays the same across genres; the amounts change.
- Rap: firmer compression, more presence, tuning fast when the style calls for it, and delays or throws on ad-libs rather than long reverbs.
- Pop: tight tuning, controlled dynamics, a bright top end, and reverb plus a tempo-synced delay.
- R&B and soul: slower tuning so runs survive, more warmth, longer and lusher reverbs.
- Rock: more saturation, less tuning, and compression that lets the voice push.
The whole chain in one plugin
An all-in-one vocal chain plugin runs these stages in the right order inside one instance, so it goes first on the vocal track. Only cleanup (noise reduction, clip gain) belongs in front of it.
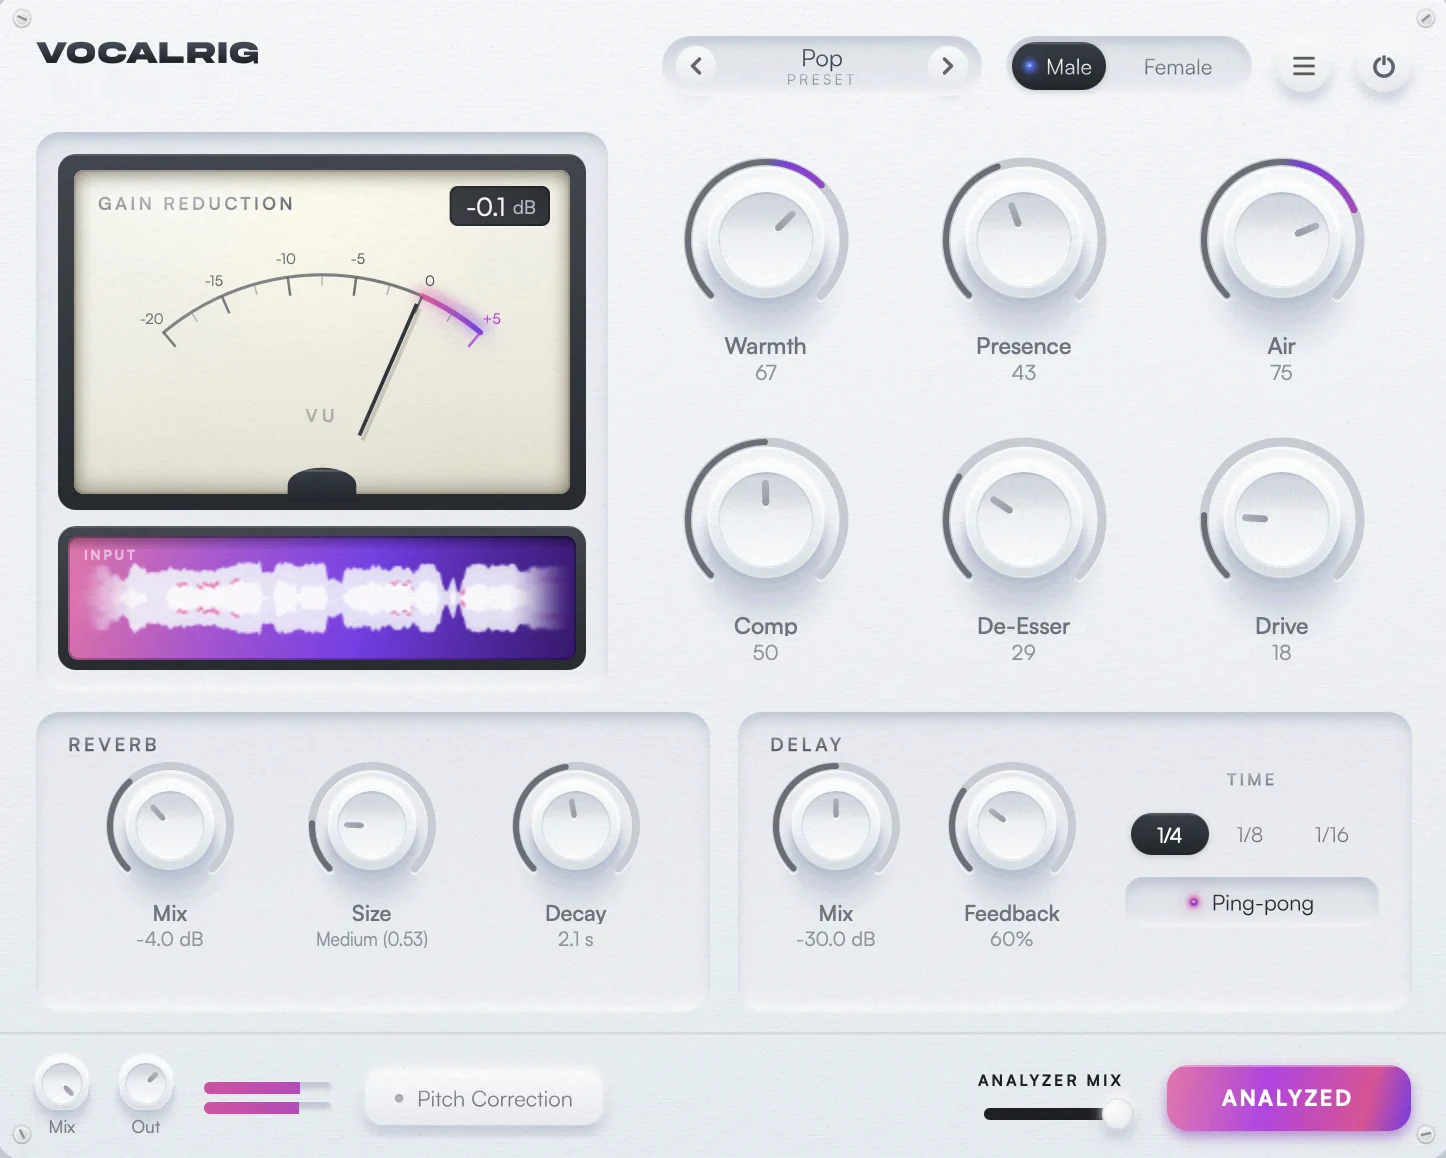
VocalRig, which we sell, is built this way. Inside one plugin it runs:
- 1Auto-LevelSlow level rides, only when Analyze decides the take needs them
- 2Pitch correctionFirst of the processors, on the clean signal
- 3Cleanup EQLow cut, shifted by the Male/Female switch
- 4Channel strip and passive tube EQInput colour, low-end weight, a smooth top
- 5Opto, then FET compressorSlow levelling, then fast peak control
- 6Air band and multiband glueSheen on top, density across the bands
- 7Auto EQ, de-esser, finishing EQAnalyze’s narrow cuts, sibilance, final balance
- 8DoublerOptional stereo doubling, 2 or 4 voices
- 9Reverb and delayParallel sends off the finished vocal
Two details worth noticing. The tuner sits ahead of every colour stage, exactly where step 2 above says it should, and reverb and delay are parallel sends off the finished vocal. Its narrow corrective cuts (the Auto EQ that Analyze writes) are dynamic and come after the compressors, while the broad cleanup happens up front. If you hand-edit pitch in a note editor, do that first and leave VocalRig’s tuner off. For recording, its Tracking Mode mutes the reverb and delay to save CPU; the reported latency stays around 1.5 ms either way.
Comparing options first? Our ranking of the best vocal chain plugins lists ten, with prices and formats. For everything VocalRig does, see the VocalRig guide.
Common vocal chain mistakes
Most bad vocal chains have the right plugins in the wrong order, or too many plugins doing the same job.
- Tuning after reverb or saturation. The tracker hears the effect, not the voice. Tune first.
- Boosting into the compressor. Every boost before it changes what it reacts to. Cut before, boost after.
- Three compressors each doing 8 dB. Stacked compression should share the work in small amounts.
- Judging changes at different volumes. Louder sounds better to everyone, briefly. Match levels before you compare.
- Monitoring through a slow chain while recording. If the singer hears themselves late, the take suffers. Track light, mix heavy.
Frequently asked questions
What is the correct order for a vocal chain?
Cleanup first (noise reduction, clip gain, high-pass filter), then pitch correction, corrective EQ, compression, a de-esser, tone EQ and saturation, an optional limiter, and reverb and delay last on parallel sends. Clean before you shape, tune before you compress, and add space at the end.
Should EQ go before or after compression on vocals?
Both, for different jobs. Cuts go before the compressor, so it doesn’t react to mud or resonances you were going to remove anyway. Boosts usually go after it, because boosting into a compressor just makes it compress harder.
Does the de-esser go before or after the compressor?
After, as a rule: compression raises the quieter parts of the signal, and S sounds come up with them. If loud S sounds are triggering the compressor, add a light de-esser before it as well.
Where does Auto-Tune go in a vocal chain?
Near the top, right after cleanup and before compression, saturation and reverb. A pitch tracker reads the shape of the waveform, and everything that colours or smears the signal makes that harder. If you hand-edit pitch in a note editor, do that first, as an edit, before the chain.
Should vocal reverb be an insert or a send?
A send, in most mixes. Sending the vocal to a reverb on an aux track keeps the dry vocal untouched, lets several tracks share one space, and lets you EQ the reverb return on its own. An insert with a mix knob works too; it’s just harder to manage once the session grows.
The order, one more time
Clean, tune, cut, compress, de-ess, colour, space. Then stop adding plugins.